Chapter 4
Maths Foundations: Calculus & Optimisation
Chapter 3 gave linear regression a closed-form solution: the normal equations solve for the exact optimum in one step. The underlying loss surface is a simple quadratic bowl, with a single minimum reachable by matrix algebra. That trick doesn’t generalise. Logistic regression, neural networks, and nearly every other model this book covers have no closed-form solution. They have to be found by search, starting from a random guess and iteratively improving it until the loss is small enough. This chapter is about that search. What a gradient is. Why walking downhill on a loss surface finds good parameters. Why step size matters so much. Why the chain rule of calculus, applied billions of times per training run, is the entire mechanism behind training a neural network. Everything from logistic regression in Chapter 11 through fine-tuning language models later in this series runs on the ideas in this chapter.
4.1 Motivation
Training a model is optimisation: find the parameters that minimise a loss function measuring how wrong the model’s predictions are. The loss function defines a surface over parameter space. For a model with two weights, imagine literal terrain, with height at each point equal to the loss for those two weight values.
Training is the search for the lowest point in that terrain. Gradient descent is the specific search algorithm this book relies on almost everywhere: stand where you are, work out which direction goes downhill steepest, take a step, repeat. It scales from a single-parameter toy problem to models with hundreds of billions of parameters. That’s why it, not exact algebraic solutions, is the workhorse of modern machine learning.
4.2 Exposition
4.2.1 Derivatives and Gradients
A derivative measures a function’s rate of change at a point. You already have an intuition for this from somewhere far more familiar than calculus class. Velocity is the derivative of position with respect to time: how fast something is moving, right now. Acceleration is the derivative of velocity with respect to time: how fast the speed itself is changing. A car’s speedometer is displaying a derivative in real time, and pressing the accelerator changes a derivative of a derivative. For a function , the derivative evaluated at asks the same question in general form: if increases by a tiny amount, how much does change, and in which direction? The sign carries the information that matters for optimisation. If , is increasing at , so decreasing reduces . If , the reverse. If , the function is momentarily flat, a candidate minimum, maximum, or saddle point.
Real loss functions depend on many parameters at once: one weight per feature, easily thousands in a modest model. The multivariate generalisation of the derivative is the gradient, , the vector of partial derivatives, one per parameter:
Each entry says how the loss responds to nudging that one parameter while holding the others fixed. The gradient vector as a whole points in the direction of steepest ascent of . To reduce the loss, step in the opposite direction. That’s the basis of gradient descent.
4.2.2 Gradient Descent
The update rule follows directly from the previous section:
where is the current parameter vector, (the learning rate) controls how large a step to take, and is the gradient of the loss at the current parameters. Repeating this update (recompute the gradient, take a step, recompute, take another step) is gradient descent. It ends, in practice, when the loss stops decreasing meaningfully (convergence), or after a fixed number of iterations.
Nothing in this rule requires knowing the shape of the whole loss surface in advance. Gradient descent only ever needs the local slope at the current position. That’s exactly why it scales to problems too large to visualise or solve algebraically.
4.2.3 The Learning Rate
The learning rate governs a trade-off in every iterative optimiser, and there’s no universal right answer for it.
Too large, and each step overshoots the minimum. The parameters bounce past the bottom of the bowl, land higher up the opposite wall. The loss oscillates or diverges outright, getting worse with each iteration instead of better. Too small, and steps barely move the parameters. Training still converges eventually. But it may take orders of magnitude more iterations, and so far more compute and wall-clock time, to get there. Just right produces steady, roughly monotonic loss decrease that levels off near a minimum.
A sequence is monotonic if it only moves in one direction: always decreasing, or always increasing, never doubling back. A “roughly monotonic” loss curve mostly falls, step after step, without bouncing up, then down, then up again along the way. It doesn’t have to fall by the same amount every step, just not reverse direction for long.
Because the correct value depends on the specific problem, the architecture, and the scale of the input data, practitioners rarely fix a single learning rate for an entire run. Learning rate schedules, which reduce over the course of training, are standard practice because “just right” tends to shrink as training approaches convergence.
4.2.4 The Chain Rule and Backpropagation
Neural networks are compositions of functions. The output of one layer is the input to the next. Computing the gradient of the loss with respect to a weight buried several layers deep requires the chain rule from calculus:
Neural network layers are functions stacked inside each other: the loss depends on the last layer’s output, which depends on the layer before that, and so on, all the way back to the first weight. The chain rule is just the rule for how a nudge ripples through a chain like that. Picture a set of gears. Turn the first gear, and it turns the second one at some ratio. The second turns the third at another ratio. How fast the last gear spins, for one turn of the first, is just those ratios multiplied straight through the chain. A derivative is a local ratio like that: how much the output moves for a small nudge to the input. Chaining functions together, , chains their local ratios together the same way the gears do. That’s the whole content of “the derivative of with respect to .” is the inner gear, is the outer one. Their local rates of change multiply to give the rate of change of the whole chain.
Applied repeatedly, layer by layer, from the loss backward to the earliest weights, this is backpropagation. It propagates the gradient of the loss backward through a network, multiplying by each layer’s local derivative along the way. Frameworks like PyTorch and TensorFlow automate this via autograd, tracking every operation done on a tensor and replaying the chain rule automatically to compute exact gradients. But the chain rule is the mechanism underneath the automation. Understanding it is what turns autograd from magic into an implementation detail.
4.2.5 Loss Functions
A loss function maps predictions and true labels to a single scalar: the number gradient descent is trying to minimise. The choice of loss function defines what “good” means for a given model. This is a modelling decision to be made as you design your solution.
Mean Squared Error (MSE), for regression:
Squaring penalises large errors disproportionately and produces a smooth function that is differentiable everywhere, convenient for gradient-based optimisation.
Binary cross-entropy, for binary classification:
This isn’t arbitrary. The ingredients aren’t new. It falls directly out of maximum likelihood estimation under the Bernoulli distribution from Chapter 3. It is zero for a perfect prediction and grows without bound as a confident prediction diverges from the truth.
Mean Absolute Error (MAE), for regression that needs to be robust to outliers:
MAE weighs every error linearly rather than quadratically. A handful of extreme outliers can’t dominate the loss the way they can under MSE. But it is not differentiable at zero, which forces optimisers to fall back on subgradients there.
4.2.6 Variants of Gradient Descent
The update rule above leaves an open question: the gradient of the loss over how much data, computed at each step? Three answers are used in practice, trading off gradient accuracy against speed.
Batch gradient descent computes the gradient over the entire training set before taking a single step. This is the most accurate gradient available. But for large datasets, one step becomes prohibitively slow to compute.
Stochastic gradient descent (SGD) computes the gradient from a single example at a time. Each individual step is nearly free to compute, but noisy. An update based on one example may not point in the true downhill direction at all. Counterintuitively, that noise isn’t always negative: it can help the optimiser escape shallow local minima that a smoother trajectory would settle into.
Mini-batch gradient descent computes the gradient over a small batch of examples, typically 32, 64, 128, or 256 at a time. This is the practical compromise used throughout neural network training. Batches are large enough to average out most of the single-example noise. Small enough to keep each step fast. And a natural fit for GPU parallelism.
4.2.7 Momentum and Adam
Plain gradient descent treats every step independently, with no memory of where it has already been. That makes it slow to cross flat regions, and prone to zig-zagging in narrow, curved valleys. Two refinements address this.
Momentum accumulates a running velocity that blends the new gradient with the previous step’s direction:
Consistent gradient directions reinforce each other and accelerate. Oscillating directions partially cancel and dampen. The effect is qualitatively like a ball rolling downhill, carrying momentum through small bumps rather than reacting to every local wiggle.
Adam (Adaptive Moment Estimation) goes further, combining momentum with a per-parameter adaptive learning rate. It tracks both a running average of the gradient (like momentum) and a running average of the squared gradient. Then it scales each parameter’s step inversely with the typical magnitude of that parameter’s recent gradients. Parameters with consistently large gradients get smaller effective steps. Parameters with small gradients get larger ones. The practical consequence is that Adam is less sensitive to the initial choice of learning rate than SGD. That’s why it is the default optimiser for training neural networks.
4.2.8 When scipy Can Help, and When It Can’t
For classical, low-dimensional optimisation problems (fitting a curve, tuning a handful of hyperparameters, minimising a smooth well-behaved function), scipy.optimize.minimize provides solvers that are faster and more reliable than a hand-rolled gradient descent loop. It is the right tool for hyperparameter search, fitting statistical models, and any smooth optimisation that can use the full dataset at every step. Its L-BFGS-B solver handles millions of parameters on such problems. (minimize defaults to BFGS when there are no bounds, and to L-BFGS-B when there are.)
It is not a substitute for mini-batch gradient descent when training a neural network, for three reasons. First, L-BFGS-B needs exact, low-noise gradients. Its line search and its curvature estimates are built on full-batch gradients, and mini-batch noise breaks both. Second, mini-batch stochasticity is not noise we want to eliminate. It is how SGD and Adam escape saddle points that riddle non-convex loss surfaces. Third, realistic training data rarely fits in memory all at once. Batch-by-batch processing is required regardless of which optimiser is used. Memory for the solver itself is not the obstacle. The “L” in L-BFGS stands for limited-memory: it keeps only the last few gradient differences, typically about 10 pairs, so its memory grows linearly with the parameter count. The square-size cost belongs to exact Newton’s method, which stores the full Hessian.
4.3 Trade-offs and Limits
Convex versus non-convex loss surfaces. For a convex loss function (logistic regression’s is one example), gradient descent with a small enough learning rate is guaranteed to reach the global minimum. A convex bowl has no other minima to get stuck in. Too large a learning rate still diverges, as the Worked Example shows. Neural network loss surfaces are not convex. They are riddled with local minima and saddle points. Gradient descent finds a good minimum, not provably the best one.
Recall the terrain from this chapter’s Motivation: for a model with two weights, height at each point is loss. A convex loss function is that terrain shaped like a single bowl, one valley, one lowest point, no way to get stuck anywhere else. A non-convex loss function is terrain like this instead:
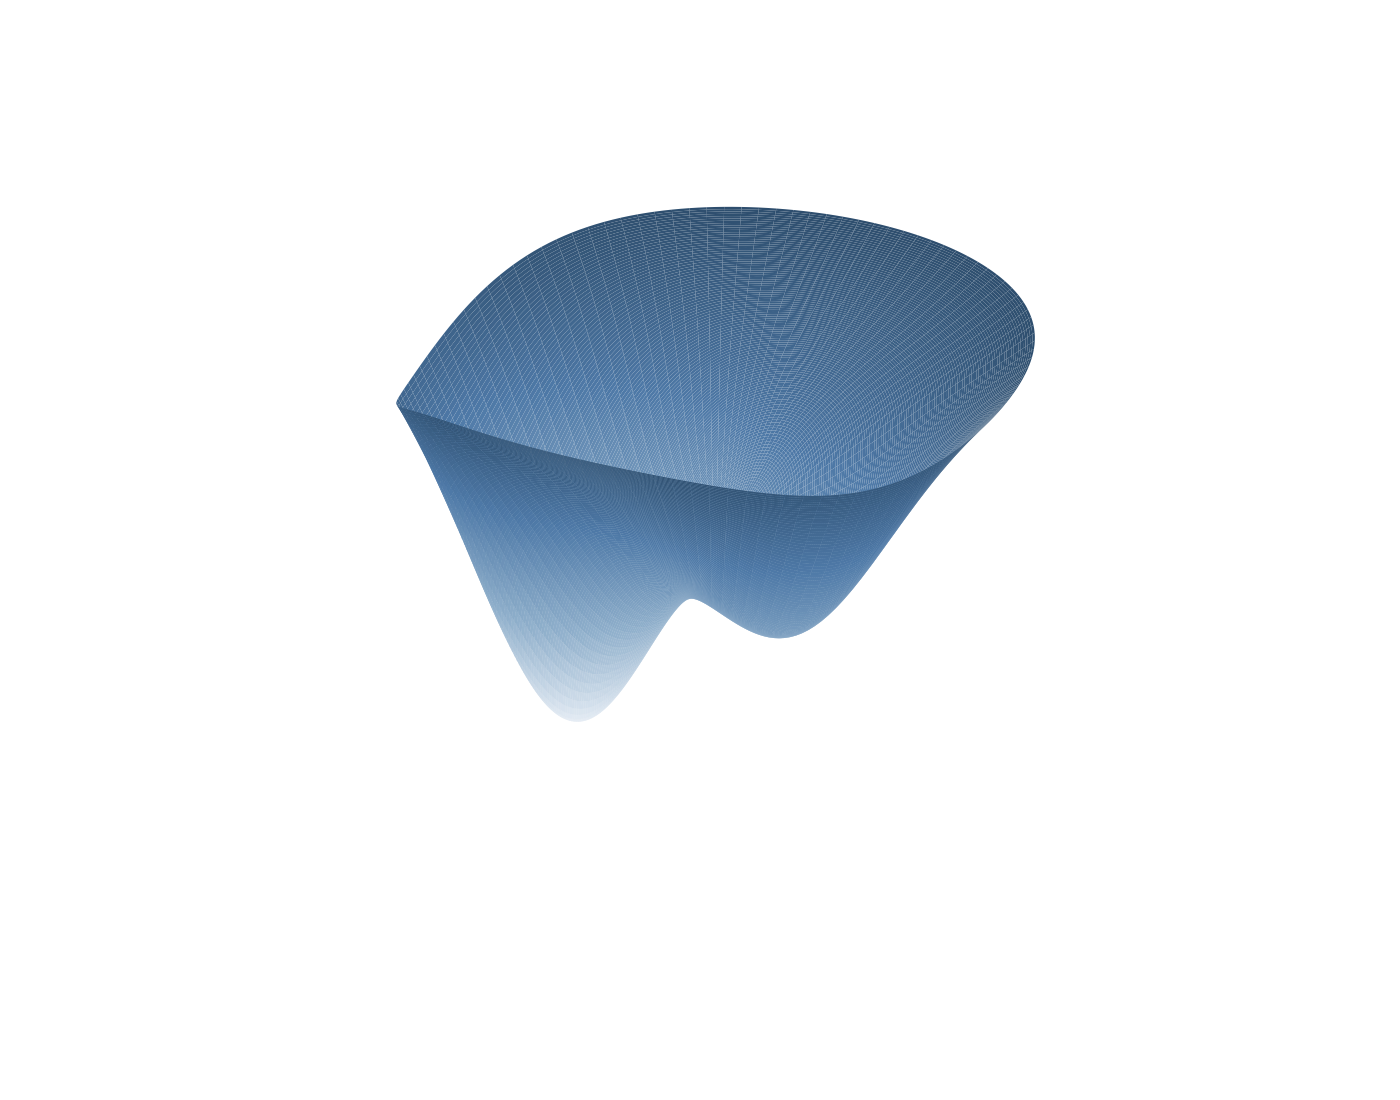
Gradient descent dropped into the shallow valley on the right has no way to know the deeper one exists. Every direction from its floor goes up, so it stops, converged, and wrong about being done. That is what “riddled with local minima and saddle points” looks like on real terrain, not just as a phrase.
In practice, for large neural networks, the local minima found this way tend to generalise well regardless. This is an empirical observation about large models. Not a theorem.
First-order versus second-order methods. Gradient descent uses only first derivatives, the slope. Newton’s method and its relatives also use second derivatives: curvature, captured in the Hessian matrix. That lets them converge in far fewer iterations near a minimum. The catch is that the Hessian is an matrix for parameters, so storing and inverting it becomes infeasible long before reaches the billions-to-trillions scale of modern neural networks. Limited-memory quasi-Newton methods such as L-BFGS avoid storing it, but they need exact, full-batch gradients, which neural network training doesn’t have. This is why first-order adaptive methods like Adam, not second-order methods, dominate deep learning. The trade-off is convergence speed per step, against whether the method can run at all. At GenAI scale that’s barely a contest: second-order methods can’t run at that size to begin with.
4.4 Procedures
Procedure 4.1 (Choose a Starting Learning Rate). When to use: at the start of any training run, before the first real epoch.
import numpy as np

def lr_range_test(X, y, lr_min=1e-5, lr_max=1.0, n_trials=30):
    """Quick scan to find a reasonable learning-rate range."""
    lrs = np.logspace(np.log10(lr_min), np.log10(lr_max), n_trials)
    final_losses = []
    for lr in lrs:
        w = np.zeros(X.shape[1])
        for _ in range(50):  # short run
            w = w - lr * mse_gradient(w, X, y)
        final_losses.append(mse_loss(w, X, y))
    best_lr = lrs[np.argmin(final_losses)]
    return best_lr, lrs, final_losses

# Rule-of-thumb starting points:
#   simple linear/logistic models:  lr = 0.1
#   neural networks (Adam default): lr = 1e-3
#   fine-tuning large models:       lr = 1e-5 to 5e-5
#   XGBoost:                        lr = 0.05 to 0.3
Common mistake: picking a learning rate once and never revisiting it. A rate that is “just right” early in training is frequently too large once the loss has mostly converged, which is the problem learning rate schedules (Procedure 4.4) exist to solve.
Procedure 4.2 (Read a Loss Curve). When to use: after every training run, as the first diagnostic before touching any hyperparameter.
import matplotlib.pyplot as plt

def plot_loss_curve(
    train_losses, val_losses=None, title='Training Loss'
):
    plt.figure(figsize=(10, 4))
    plt.plot(
        train_losses,
        label='Train loss', color='#4E79A7', linewidth=2,
    )
    if val_losses is not None:
        plt.plot(
            val_losses,
            label='Validation loss',
            color='#E15759', linewidth=2,
        )
    plt.xlabel('Epoch')
    plt.ylabel('Loss')
    plt.title(title)
    plt.legend()
    plt.tight_layout()
    plt.show()

patterns = {
    "Steadily decreasing": "Good: model is learning",
    "Decreasing then plateau": (
        "Good: converged. More epochs won't help"
    ),
    "Oscillating": "Learning rate too high: reduce by 3-10x",
    "Train low, val high": (
        "Overfitting: add regularisation or more data"
    ),
    "Both high, not decreasing": (
        "Underfitting: model too simple, or LR too low"
    ),
    "NaN or infinity": (
        "Learning rate too high, or a numerical issue"
    ),
}
Procedure 4.3 (Use scipy.optimize for Classical Optimisation). When to use: smooth optimisation that can use the full dataset at every step, curve fitting, or whenever a precise minimum matters more than raw training speed.
import scipy.optimize as opt
import numpy as np

def my_loss(params):
    w0, w1 = params
    predictions = w0 + w1 * X
    return np.mean((predictions - y) ** 2)

def my_gradient(params):
    w0, w1 = params
    residuals = (w0 + w1 * X) - y
    return np.array([
        2 * np.mean(residuals),
        2 * np.mean(residuals * X),
    ])

result = opt.minimize(
    fun=my_loss, x0=[0.0, 0.0],
    jac=my_gradient,     # supplying the gradient converges faster
    method='L-BFGS-B', options={'maxiter': 1000, 'ftol': 1e-9}
)
print(result.success, result.x, result.fun)
Common mistake: reaching for scipy.optimize.minimize on a neural network because “it converges faster” on small problems. See this chapter’s Exposition on why scipy’s solvers don’t suit neural network training. Exact Newton methods can’t store the Hessian past tens of thousands of parameters. L-BFGS-B can run at that size, but it needs exact, full-batch gradients.
Procedure 4.4 (Schedule a Decaying Learning Rate). When to use: training runs long enough that a single fixed learning rate is a poor fit across the whole run.
import numpy as np

def step_decay(initial_lr, epoch, drop=0.5, epochs_drop=20):
    return initial_lr * (drop ** (epoch // epochs_drop))

def cosine_decay(initial_lr, epoch, total_epochs):
    return initial_lr * 0.5 * (
        1 + np.cos(np.pi * epoch / total_epochs)
    )

def warmup_cosine(initial_lr, epoch, warmup_epochs, total_epochs):
    if epoch < warmup_epochs:
        # epoch + 1, so the first epoch already makes an update
        return initial_lr * (epoch + 1) / warmup_epochs
    return cosine_decay(
        initial_lr,
        epoch - warmup_epochs,
        total_epochs - warmup_epochs,
    )
Procedure 4.5 (Spot Vanishing or Exploding Gradients). When to use: a neural network’s loss refuses to decrease, or diverges outright, and the learning rate alone doesn’t explain it.
def check_gradient(grad, name='gradient'):
    norm = np.linalg.norm(grad)
    if norm < 1e-7:
        print(f"WARNING: {name} may be vanishing "
              f"(norm={norm:.2e})")
    elif norm > 100:
        print(f"WARNING: {name} may be exploding "
              f"(norm={norm:.2e})")
    else:
        print(f"  {name} norm: {norm:.4f}  (healthy)")
    return norm

# In PyTorch (autograd tracks gradients per parameter,
# automatically):
#   for name, param in model.named_parameters():
#       grad_norm = param.grad.norm().item()
# Standard fix for exploding gradients:
#   torch.nn.utils.clip_grad_norm_(
#       model.parameters(), max_norm=1.0
#   )
Common mistake: treating every diverging loss as a learning-rate problem. A loss that goes to NaN after training stably for many epochs is more often exploding gradients deep in the network than a suddenly-wrong learning rate. Check gradient norms (Listing 4.5) before cutting .
4.5 Worked Example
The companion notebook builds gradient descent up in three stages. It starts on a toy 1D parabola. It moves to a real linear regression problem where the answer can be checked independently. It ends with a comparison across three learning rates, which makes the “too large / too small / just right” trade-off concrete.
Stage 1 — gradient descent on . With df(x) = 2*x, starting at and a learning rate of 0.2, running the update rule for 20 steps:
def gradient_descent_1d(start_x, learning_rate, n_steps):
    x = start_x
    history = [(x, f(x))]
    for step in range(n_steps):
        gradient = df(x)
        x = x - learning_rate * gradient
        history.append((x, f(x)))
    return history

history = gradient_descent_1d(
    start_x=3.0, learning_rate=0.2, n_steps=20
)
The trajectory shrinks geometrically towards the true minimum at . Step 0 sits at (). By step 3 it has fallen to (). By step 7, to (). By step 20, to , with . That’s visibly geometric decay, since each step multiplies the distance to the minimum by a constant factor of for this particular and .
Stage 2 — training real linear regression by gradient descent, with an independent check. Using a synthetic 200-sample, single-feature regression dataset (make_regression, noise=20, random_state=42), standardised and with a bias column prepended. Full-batch gradient descent is run for 200 epochs at :
def train_linear_regression_gd(
    X, y, learning_rate=0.1, n_epochs=200
):
    w = np.zeros(X.shape[1])
    loss_history = []
    for epoch in range(n_epochs):
        loss = mse_loss(w, X, y)
        grad = mse_gradient(w, X, y)
        w = w - learning_rate * grad
        loss_history.append(loss)
    return w, loss_history

w_gd, loss_history = train_linear_regression_gd(
    X, y, learning_rate=0.1, n_epochs=200
)
The loss falls from 6934.10 at epoch 0 to 406.52 by epoch 40, and stays there. Training has converged before the 200-epoch budget is used up. The real test is whether gradient descent’s answer matches the two ways of getting an exact answer to the same problem: the normal equations from Chapter 3, and scikit-learn’s LinearRegression. All three agree to six decimal places: from gradient descent, from the normal equations, and from sklearn. That’s an exact match (np.allclose(..., atol=0.01) returns True). It confirms that iterative search and closed-form algebra are finding the same optimum, as convexity of the MSE loss guarantees they must.
Stage 3 — the learning rate trade-off, made concrete. Running the same training loop for 100 epochs at three learning rates:
learning_rates = {
    'Too small (0.001)': 0.001,
    'Just right (0.1)': 0.1,
    'Too large (1.5)': 1.5,
}
for label, lr_val in learning_rates.items():
    w = np.zeros(X.shape[1])
    for epoch in range(100):
        loss = mse_loss(w, X, y)
        grad = mse_gradient(w, X, y)
        w = w - lr_val * grad
At , the loss has only crawled from 6934.10 down to 4797.88 after all 100 epochs. That’s nowhere near the optimal 406.52, illustrating that “too small” is not a safety net. It’s slow. At , the loss is already down to 481.78 by epoch 10 and has essentially converged to 406.53 by epoch 30. At , the loss doesn’t decrease at all. By epoch 10 it has blown past (the notebook clips the plotted value there to keep the chart readable). That’s a clean example of divergence from overshooting, not a bug in the implementation.
Finally, the same problem solved with scipy.optimize.minimize (Procedure 4.3, L-BFGS-B with the analytic gradient supplied) converges to the identical answer (, loss ) in just 2 iterations. Gradient descent needed about 40 epochs to get there. That gap is the entire argument for Procedure 4.3’s “when to use scipy” guidance: for a 2-parameter smooth convex problem, a second-order-aware solver is better. The notebook then makes the scaling argument concrete rather than asserted. Storing the exact Hessian for a modest 1-million-parameter model, as Newton’s method does, would need bytes of float32 storage. That’s about 4,000 GB (3,725 GiB), comfortably past what even a high-end accelerator carries in memory. L-BFGS-B avoids that cost by keeping only a few recent gradient differences, so its memory grows linearly with the parameter count. What stops it at neural-network scale is the gradient: mini-batch gradients are noisy, and its line search and curvature estimates need exact ones. That’s why this approach is confined to smooth, full-batch problems, and mini-batch gradient descent (or Adam) takes over at neural-network scale.
4.6 AWS SageMaker Notes
import sagemaker
from sagemaker.estimator import Estimator

estimator = Estimator(
    entry_point='train.py',
    role=role,
    instance_type='ml.p3.2xlarge',   # GPU instance
    hyperparameters={
        'learning_rate': 0.001,
        'epochs': 100,
        'batch_size': 256,
    }
)
estimator.fit({'train': training_data_uri})
When to prefer this: SageMaker Training Jobs handle provisioning the GPU instances that gradient descent runs on. You still write the training loop (exactly the update rule from this chapter). SageMaker manages the compute underneath it. A later chapter on hyperparameter tuning replaces hand-set values like learning_rate here with SageMaker Automatic Model Tuning. That searches the hyperparameter space via Bayesian optimisation instead.
4.7 History and Further Reading
Murphy’s Introduction, Ch. 8, covers optimisation theory, gradient-based methods, and convergence proofs in more formal depth than this chapter attempts (Murphy 2022). Burkov, Ch. 3, walks through gradient descent concisely using logistic regression as the running example. That’s a useful second pass on the same material from a different angle (Burkov 2019). Géron’s Hands-On Machine Learning, Ch. 4, walks through batch, stochastic, and mini-batch gradient descent side by side in code. It’s useful for seeing this chapter’s update rule run (Géron 2019). Two resources outside the shared bibliography are worth the reader’s time directly. Gabriel Goh’s “Why Momentum Really Works” (distill.pub, 2017) gives an illuminating visual account of momentum. 3Blue1Brown’s “Backpropagation” video is, among the many available explanations, the clearest visual walkthrough of the chain rule as it plays out inside a neural network.
4.8 How This Connects
This chapter builds directly on Chapter 3’s linear algebra and its normal-equations solution to linear regression. This chapter’s Worked Example uses that exact solution as the independent check for gradient descent’s answer. It enables every model in the rest of this book. Logistic regression, the tree ensembles and neural networks that follow, and the fine-tuning procedures in later volumes all reduce, at some level, to the update rule in this chapter’s Exposition. It is often confused with the loss function. But gradient descent is the how of minimisation, and the loss function is the what being minimised. Chapter 5’s cross-entropy and KL divergence supply another important instance of the “what,” measured in the specific language of probability distributions.
4.9 Exercises
[W] Explain in your own words why points in the direction of steepest ascent, and why gradient descent then steps in the negative gradient direction.
[W] A training run’s loss oscillates wildly between epochs 5 and 40, then goes to NaN at epoch 41. Using Listing 4.2’s diagnostic table, name the most likely cause and the first thing to try.
[A] Using Listing 4.6, rerun gradient descent on starting at with learning rate instead of . Report what happens to over the first 5 steps. Explain it in terms of the contraction factor mentioned in the Worked Example.
[A] Using Listing 4.7, rerun training with
learning_rate=0.5instead of0.1for 200 epochs, and report the epoch at which the loss first comes within 1% of the optimal loss (406.52), compared to the ~17 epochs it took at .[A] Using Listing 4.8 as a starting point, add a fourth learning rate of your choosing between 0.1 and 1.5, run it for 100 epochs. Classify it as behaving more like “just right” or “too large,” based on where the loss lands by epoch 30.
[E] The chapter states that Adam’s adaptive per-parameter scaling makes it “less sensitive to the initial choice of learning rate than SGD.” Propose an experiment (you don’t need to run it) that would test this claim directly against plain SGD. State what result would falsify it.
[E] A colleague proposes using
scipy.optimize.minimizewithmethod='L-BFGS-B'to fine-tune a 50-million-parameter neural network because “it converged in 2 iterations on our small test problem.” Using this chapter’s argument on why scipy’s solvers don’t suit neural network training, write the two or three sentences you’d say to redirect them.[R] Read Goh’s “Why Momentum Really Works” (cited above). Explain, in terms distinct from this chapter’s “rolling ball” intuition, why momentum specifically helps in loss surfaces shaped like a narrow curved valley (an ill-conditioned quadratic). Explain how that differs from the plain “escapes local minima via noise” story told about SGD.
4.10 Mental Model
Training a model is hiking downhill in darkness. You can’t see the whole landscape. Only which way is downhill from where you’re currently standing. Gradient descent is the algorithm for taking a step based on that local slope. The learning rate is how big a step to take. Adam adds a kind of adaptive GPS, scaling each direction’s step size based on how steep that particular direction has been recently. The chain rule is what makes it possible to compute “which way is downhill,” even when the loss is buried many layers deep inside a composed function. That’s exactly what a neural network is.